Taekyung Ki
|
I am a 2nd-year Ph.D. student at KAIST MLAI advised by Prof. Sung Ju Hwang. I am currently completing a research internship at Apple, working on multimodal diffusion models. Prior to this, I completed a three-year alternative military service in South Korea as a research scientist working on video generation. I received my M.S. and B.S. in Mathematics. I am interested in the following research topics:
|
|
|
I am open to research collaborations globally! Feel free to reach out to me if you are interested in any related topics. |
|
Highlights
|
|
AI/ML Ph.D. Research Intern
Research on multimodal diffusion models Video Computer Vision (VCV) Team @ Apple June 15, 2026 - November 30, 2026 Sunnyvale, CA, US |
|
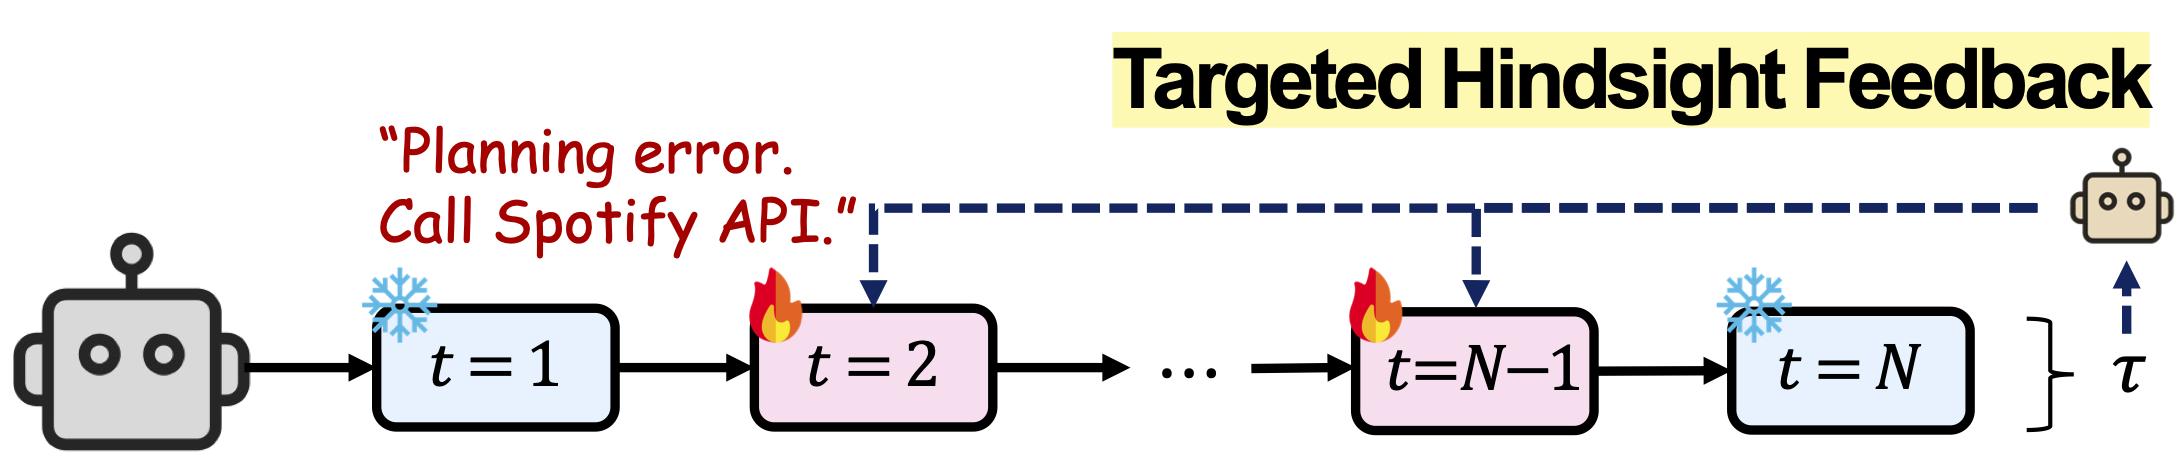
HINT-SD: Targeted Hindsight Self-Distillation for Long-Horizon Agents
Woongyeng Yeo*, Yumin Choi*, Taekyung Ki, Sung Ju Hwang† Empirical Methods in Natural Language Processing (EMNLP Findings), 2026 arXiv / Code / Hugging Face Targeted self-distillation framework that selectively distills failure-relevant actions from full trajectories to train long-horizon agent effectively. |

|
Self-Refining Video Sampling
Sangwon Jang*, Taekyung Ki*, Jaehyeong Jo*, Saining Xie, Jaehong Yoon†, Sung Ju Hwang† International Conference on Machine Learning (ICML), 2026 Project Page / arXiv / Paper / Code / Hugging Face Improving physical plausibility in video generation without any additional training or external verifiers. |

|
Avatar Forcing: Real-Time Interactive Head Avatar Generation for Natural Conversation
Taekyung Ki*, Sangwon Jang*, Jaehyeong Jo, Jaehong Yoon, Sung Ju Hwang† Conference on Computer Vision and Pattern Recognition (CVPR), 2026 Project Page / arXiv / Paper / Video / Code / Hugging Face User-interactive head generation model based on motion latent diffusion forcing and a direct preference optimization method for interactive motion. |
|
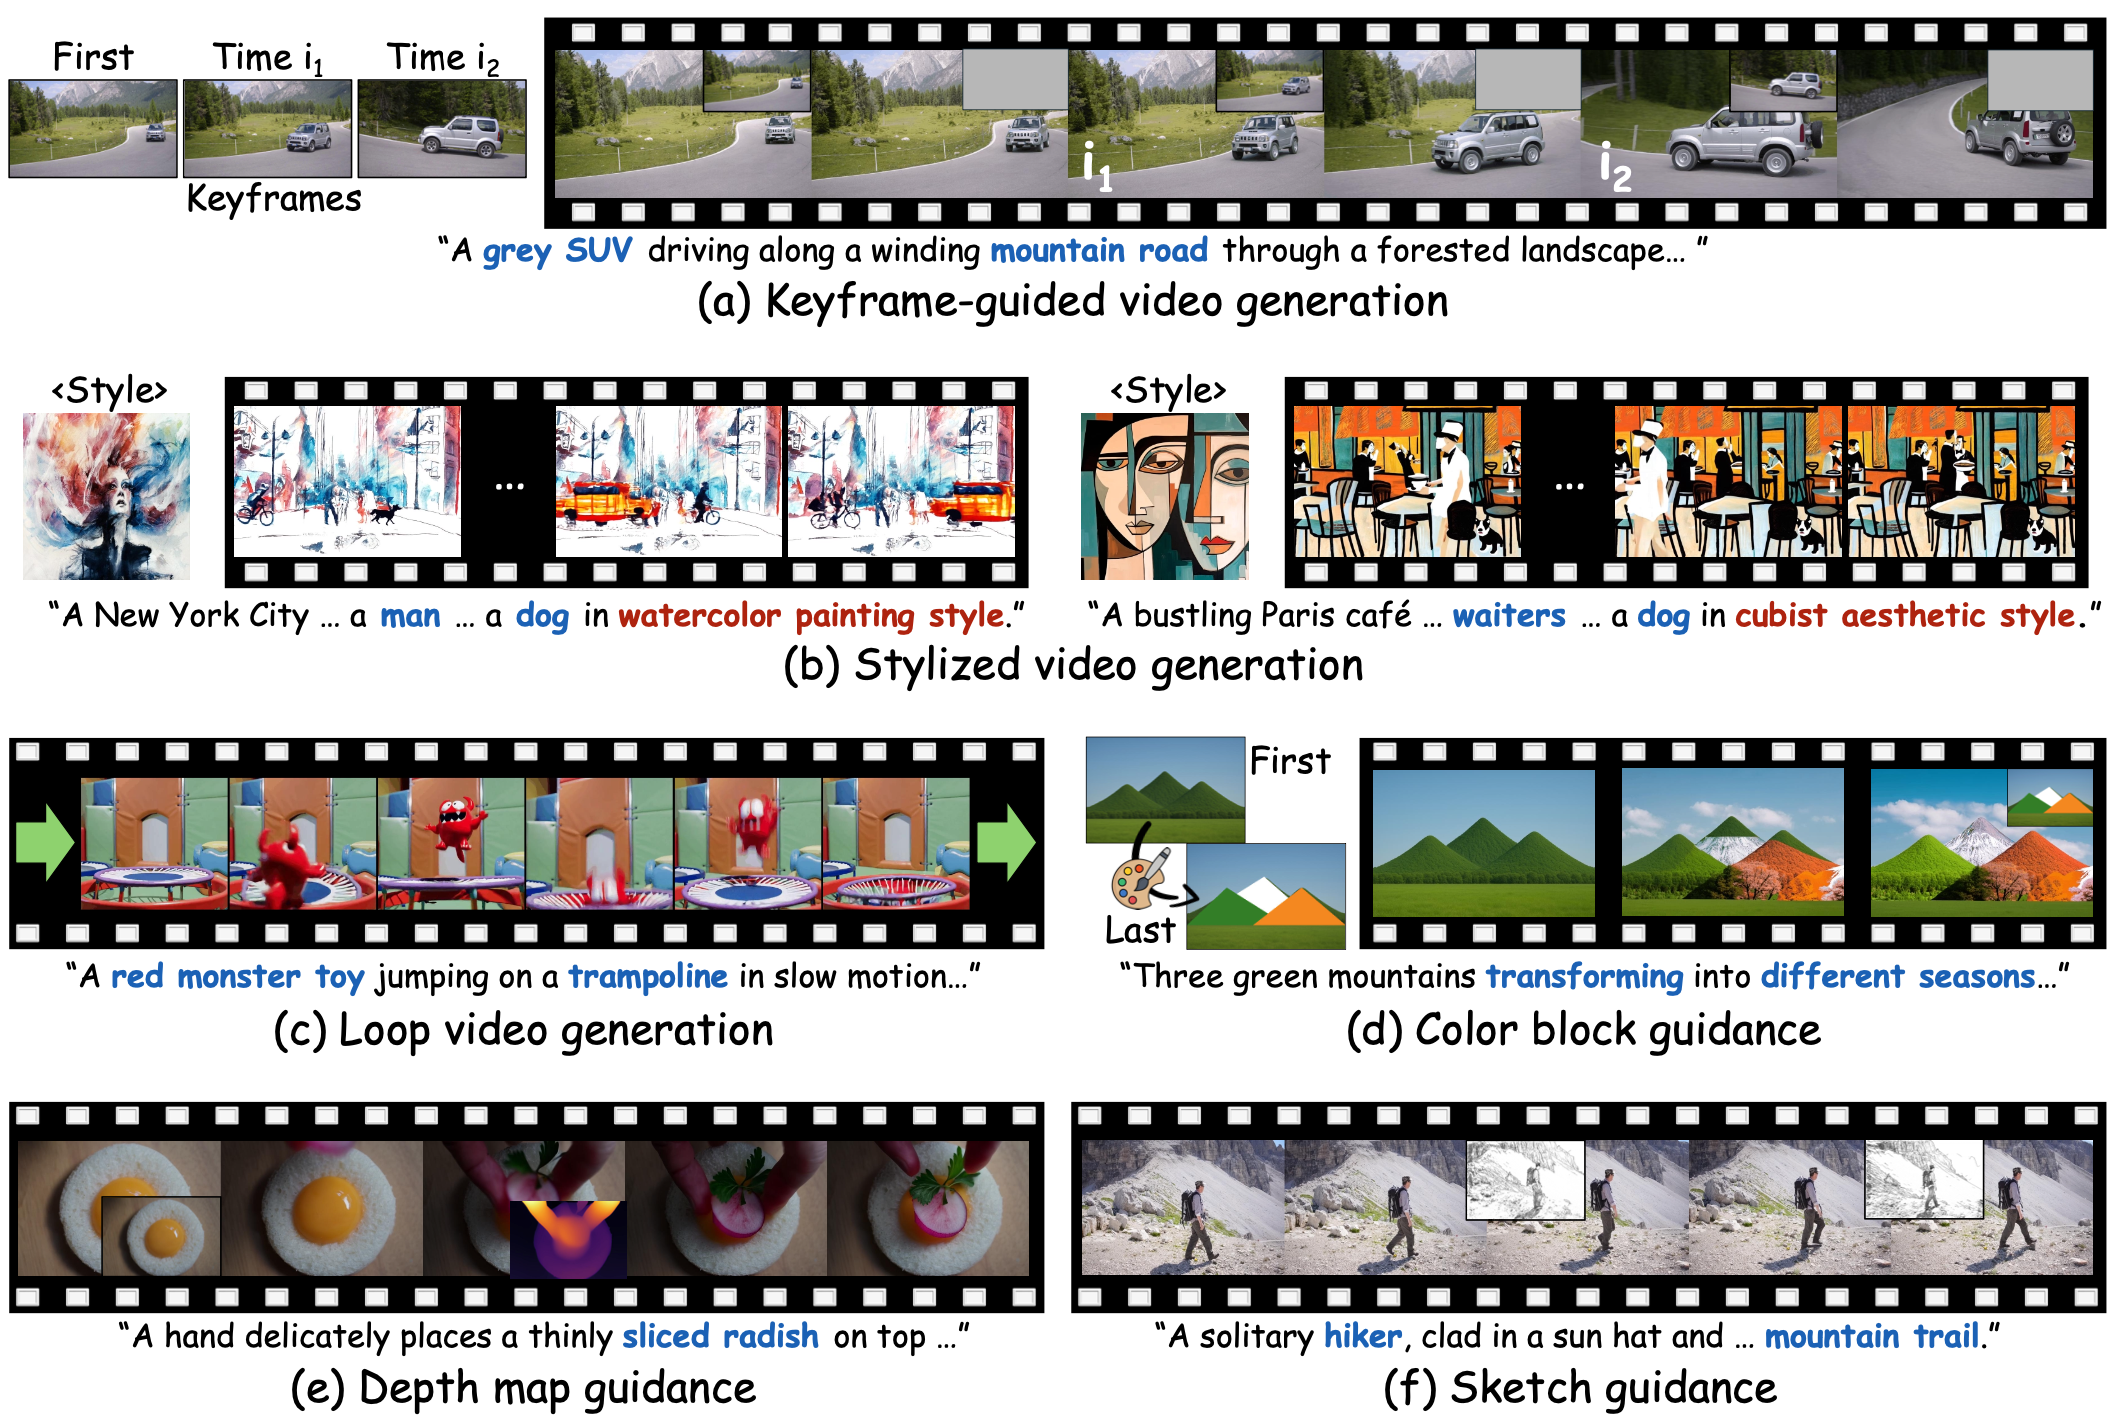
Frame Guidance: Training-Free Guidance for Frame-Level Control in Video Diffusion Models
Sangwon Jang*, Taekyung Ki*, Jaehyeong Jo, Jaehong Yoon, Soo Ye Kim, Zhe Lin, Sung Ju Hwang† International Conference on Learning Representations (ICLR), 2026 Project Page / arXiv / Paper / Code / Hugging Face Frame-level controllable training-free guidance method for large video diffusion models on a single GPU. |
|
FLOAT: Generative Motion Latent Flow Matching for Audio-driven Talking Portrait
Taekyung Ki, Dongchan Min, Gyeongsu Chae International Conference on Computer Vision (ICCV), 2025 Audio-Visual Generation & Learning Workshop at ICCV (AVGen@ICCV), 2025 Project Page / arXiv / Paper / Code / Hugging Face Motion latent flow matching for real-time audio-driven talking portrait generation and editing using the learned orthonormal motion basis. |
|
Learning to Generate Conditional Tri-plane for 3D-aware Expression Controllable Portrait Animation
Taekyung Ki, Dongchan Min, Gyeongsu Chae European Conference on Computer Vision (ECCV), 2024 Project Page / arXiv / Paper / Supp Contrastive pre-training framework for appearance-free facial expression hidden in 3DMM and 3D-aware expression-controllable portrait animation model. |
|
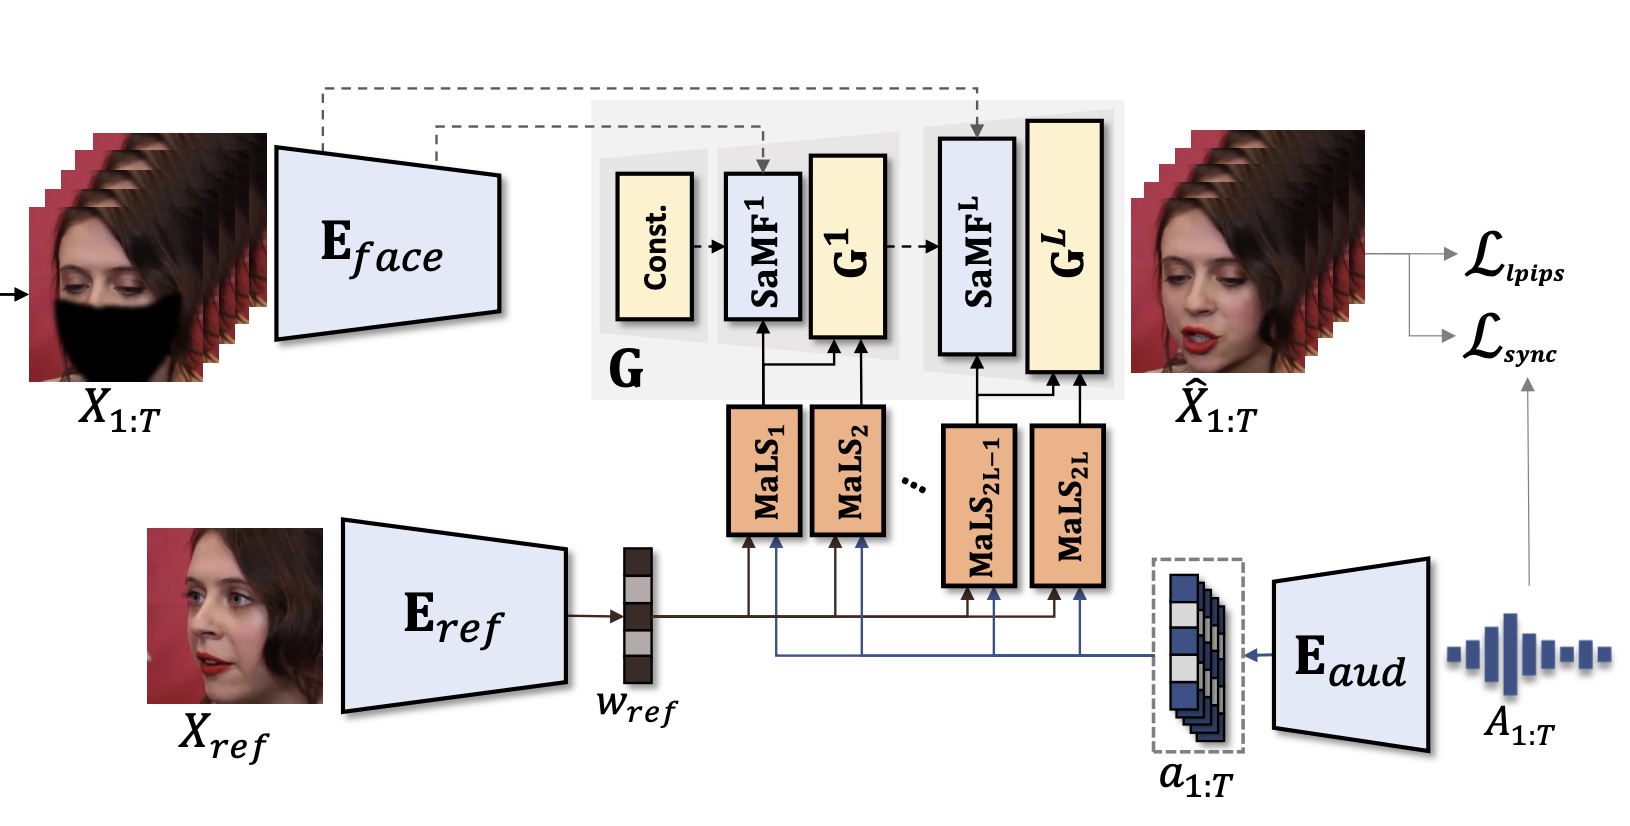
StyleLipSync: Style-based Personalized Lip-sync Video Generation
Taekyung Ki*, Dongchan Min* International Conference on Computer Vision (ICCV), 2023 Project Page / arXiv / Paper / Code / Supp StyleLipSync generates generalized and person-agnostic audio-lip synchronized videos by leveraging the strong facial prior of style-based generator. |
|
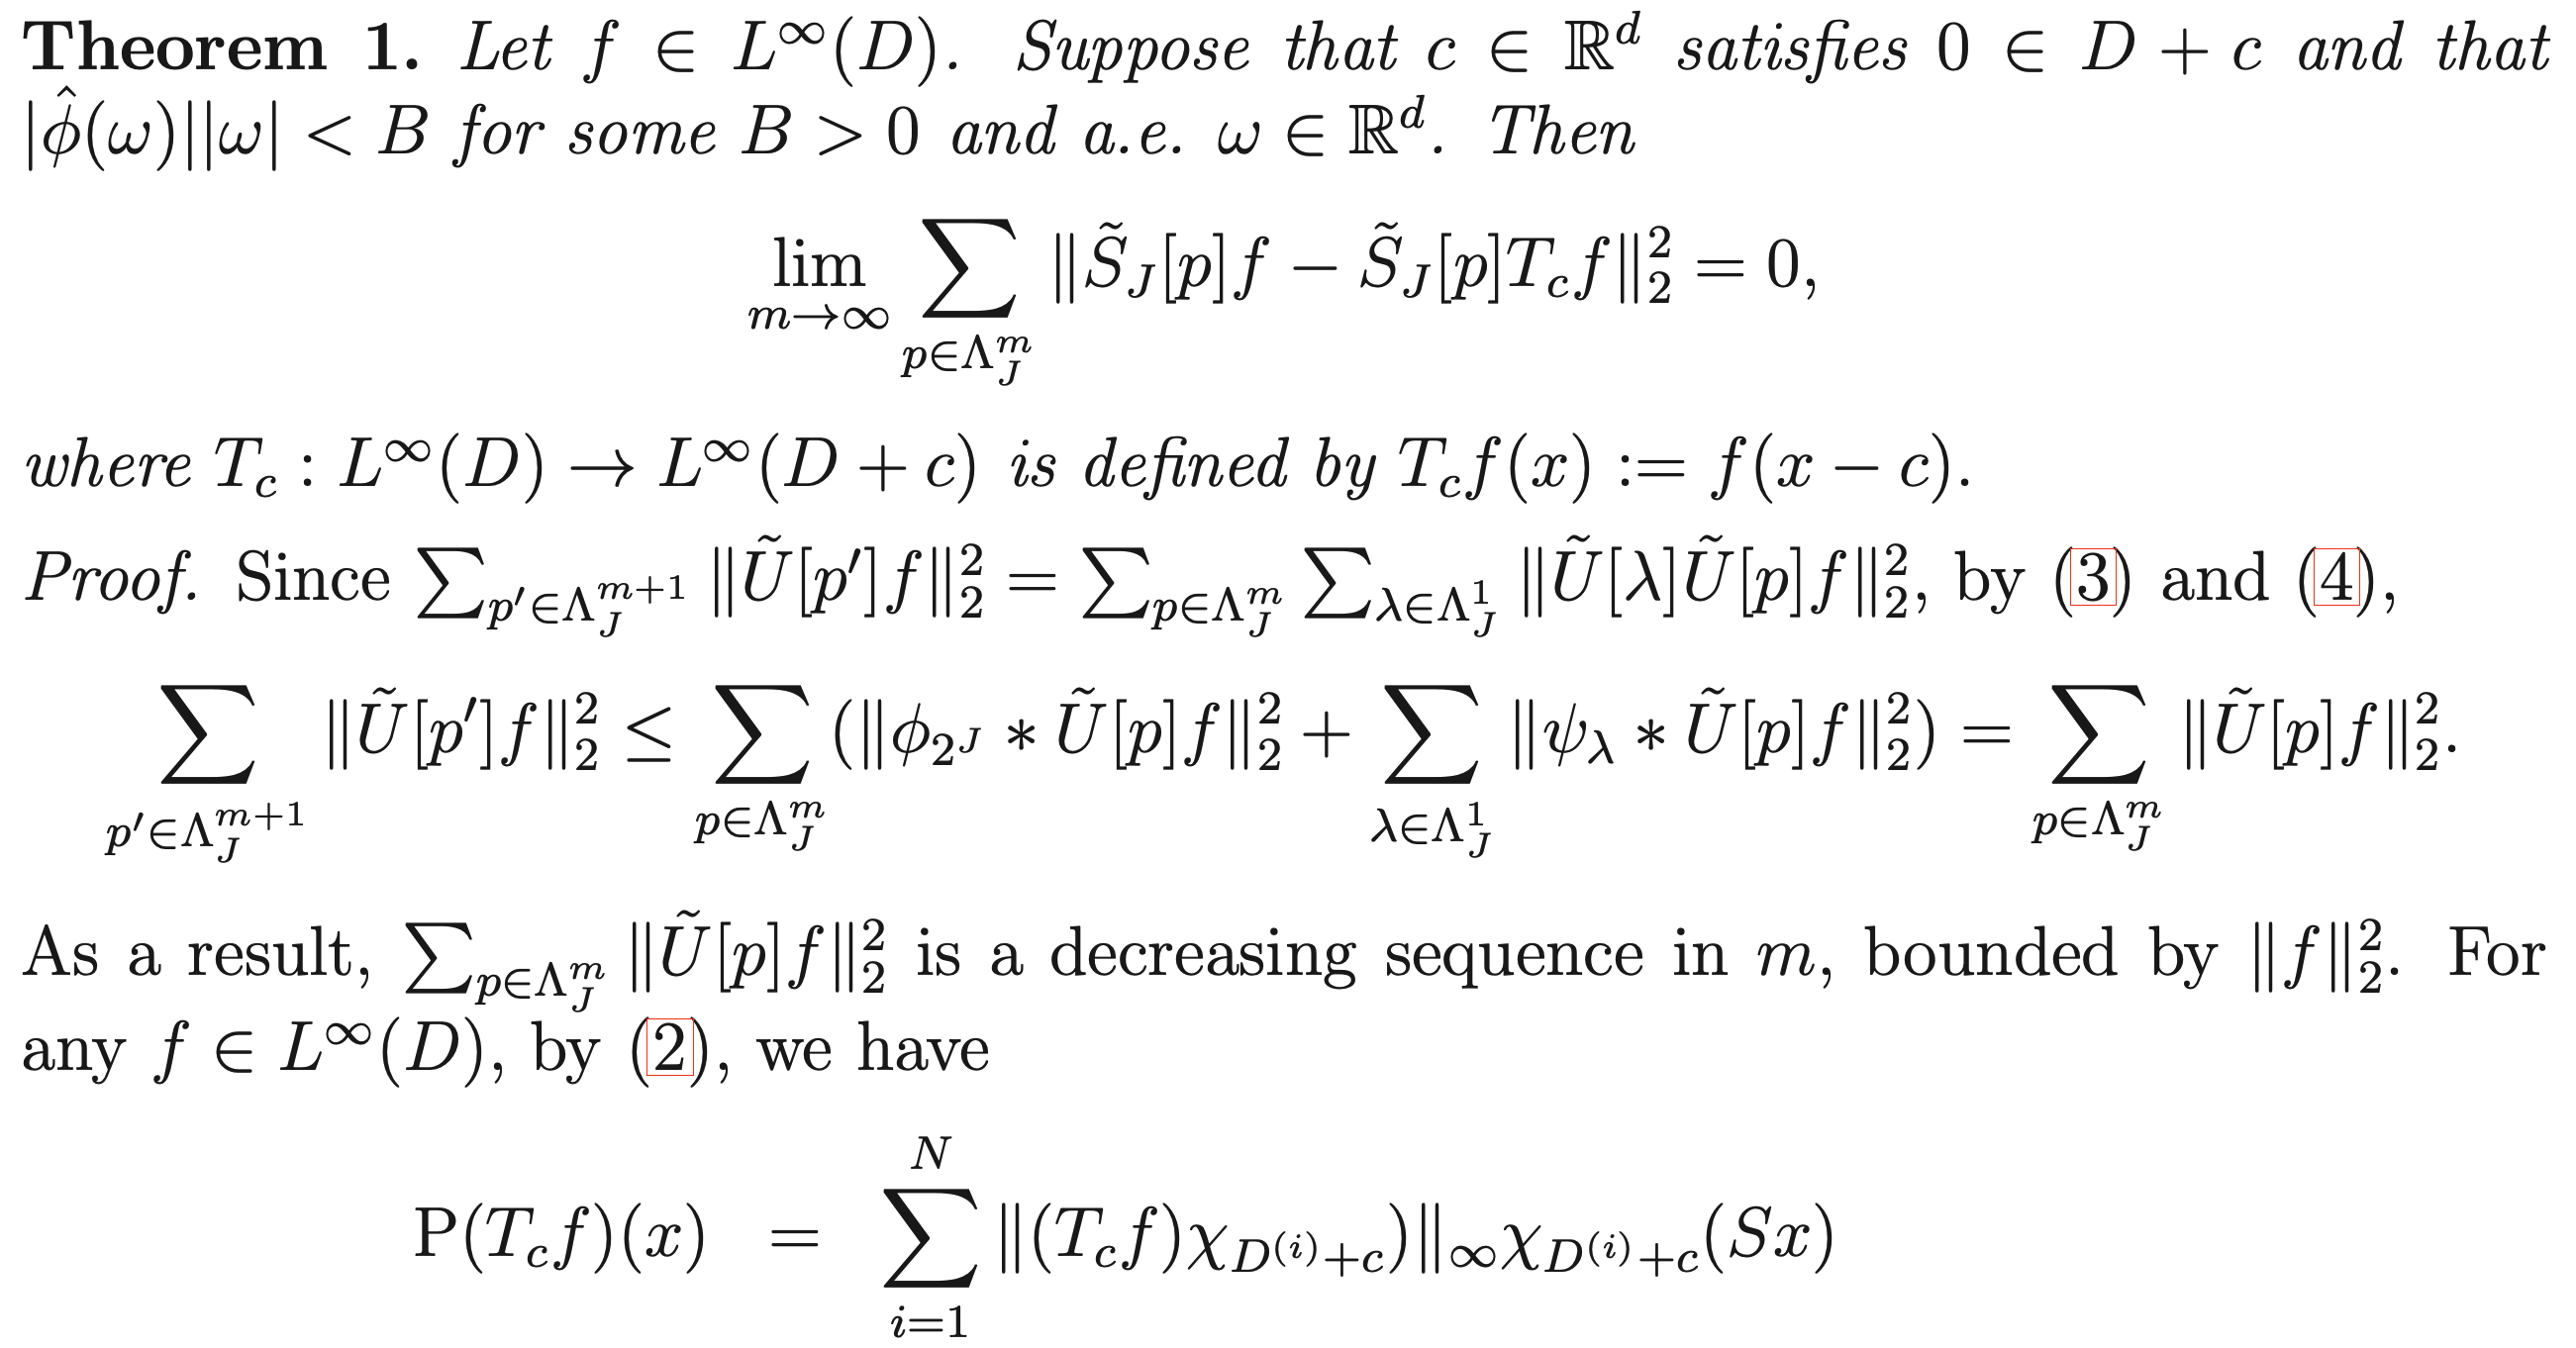
Deep Scattering Network with Max-pooling
Taekyung Ki, Youngmi Hur† IEEE Data Compression Conference (DCC), 2021 Paper / Code Proved that pooling operators allow scattering networks to extract translation-invariant features. |
|
Motion Latent Flow Matching for Real-time Audio-driven Talking Portrait
Pika Labs Host: Chenlin Meng (CTO) August 2025 |
Awards and Honors
|
Academic Services
|
|
Lastly updated in November 9, 2026. This page is based on Jon Barron's website template. |